
Data-as-a-service
Training data,built to your spec.
We source, label, review and evaluate the data your models learn from, with native Arabic annotators across 25+ dialects and domain experts in finance, healthcare, logistics and government.
Training data, done properly.
Sourced, labelled and checked by people who know the language and the domain, then delivered where it has to stay.
Quality
Labelled at 98% accuracy, with human-in-the-loop checks on every project.
Scale
30M+ data points annotated for 250+ enterprise and government organisations.
Arabic depth
Native annotators across 25+ dialects, with domain experts in finance, healthcare, logistics and government.
Kept in region
Hosted and processed in region: on-premises, hybrid or in the cloud. SOC 2 Type II and ISO 27001.
Supported data types
Every data type, labelled by people.
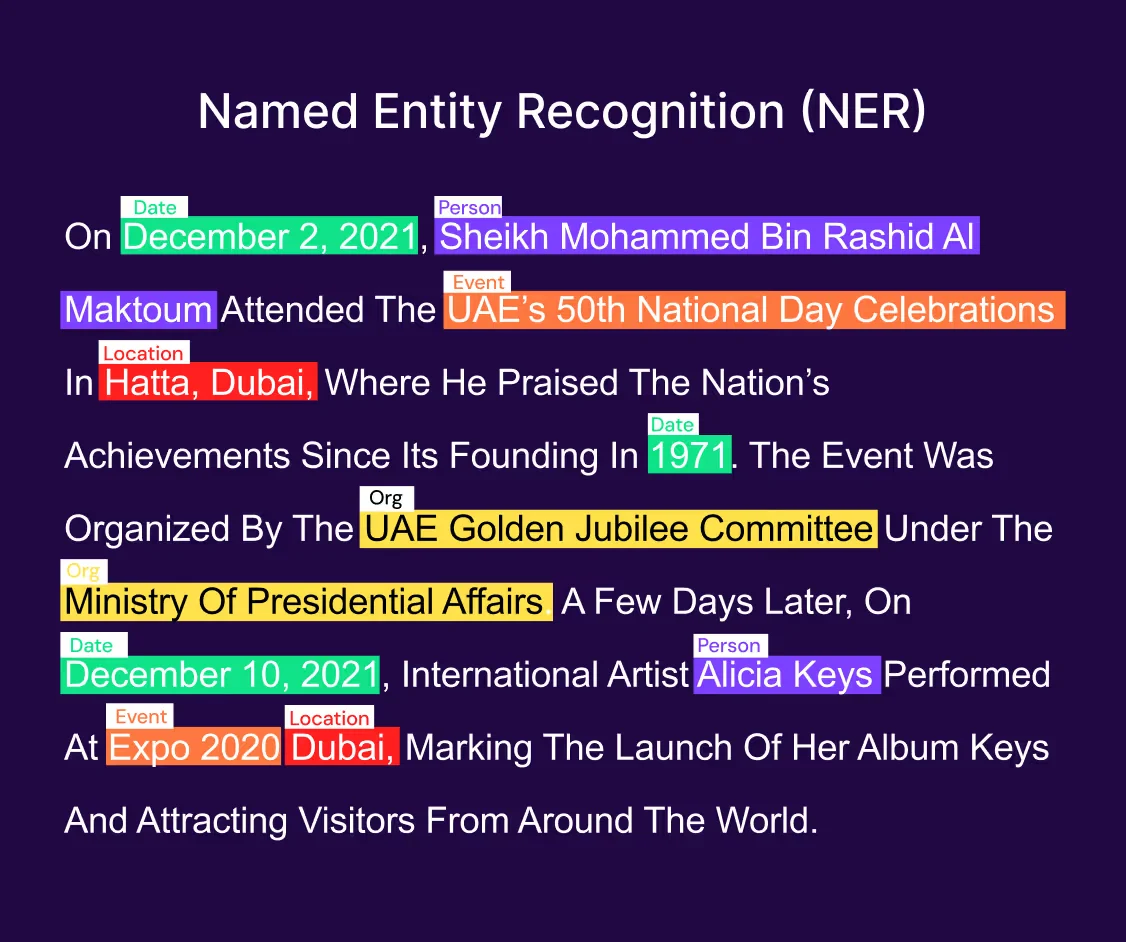
Text
Entities, sentiment, moderation and preference labels, in Arabic and English.
What we label
- Named entities
- Sentiment
- Content moderation
- Ranked model responses
Sample recordIllustrative, not customer data
{
  "text": "افتتح المعرض في دبي يوم الأحد",
  "entities": [
    { "span": "دبي", "type": "LOCATION" },
    { "span": "يوم الأحد", "type": "DATE" }
  ],
  "sentiment": "neutral",
  "reviewed_by": "native annotator"
}What we do
Four services, one data partner.
Data sourced for your model, not pulled off a shelf.
- Domain-specific datasets
- Field collection, in the places the work happens
- Integration with your enterprise systems
- Synthetic data in controlled environments
How a project runs
Every batch makes the next one better.
- 01
Scope
The model, the data behind it and the rules for labelling it.
- 02
First batch
Sourced, labelled and checked by a person before it reaches you.
- 03
Review with you
Your team reviews it. What the review finds goes into the guidelines.
- 04
Scale and deliver
The full set, delivered into your training run, kept in region.
Review findings feed the guidelines for the next batch.
The people on the line
A factory run by people, not just pipelines.
- 25+Arabic dialects
Native Arabic annotators label speech and text in the dialects people actually use.
- 67,795+People on KLKT
Contributors in 20+ countries record real work, at work or at home, and are paid per accepted hour.
- 5Evaluator specialties
Biology, medical, financial, coding and bilingual evaluators score model output.
- 4Expert domains
Domain experts in finance, healthcare, logistics and government shape every dataset.
Data catalogue
Need data that already exists?
Browse ready-made categories by modality and add them to one request.
How is this different from the data catalogue?
The catalogue lists ready-made data categories you can add to a request. Data services is a managed project: we source, label, review and evaluate data to your specification.
How accurate is the labelling?
Text, image, video and audio are labelled at 98% accuracy, with human-in-the-loop quality assurance on every project.
Who does the work?
Native Arabic annotators across 25+ dialects, domain experts in finance, healthcare, logistics and government, and human AI evaluators in biology, medicine, finance, coding and bilingual work.
How does a project start?
With discovery: the problem, the systems it touches and the data behind it. That becomes a roadmap, then a first build phase, a review, a second build phase and sign-off.
Tell us what your model needs to learn.
Share the task, the languages and the volume. We come back with a scope, guidelines and a first batch.